Synopsis:
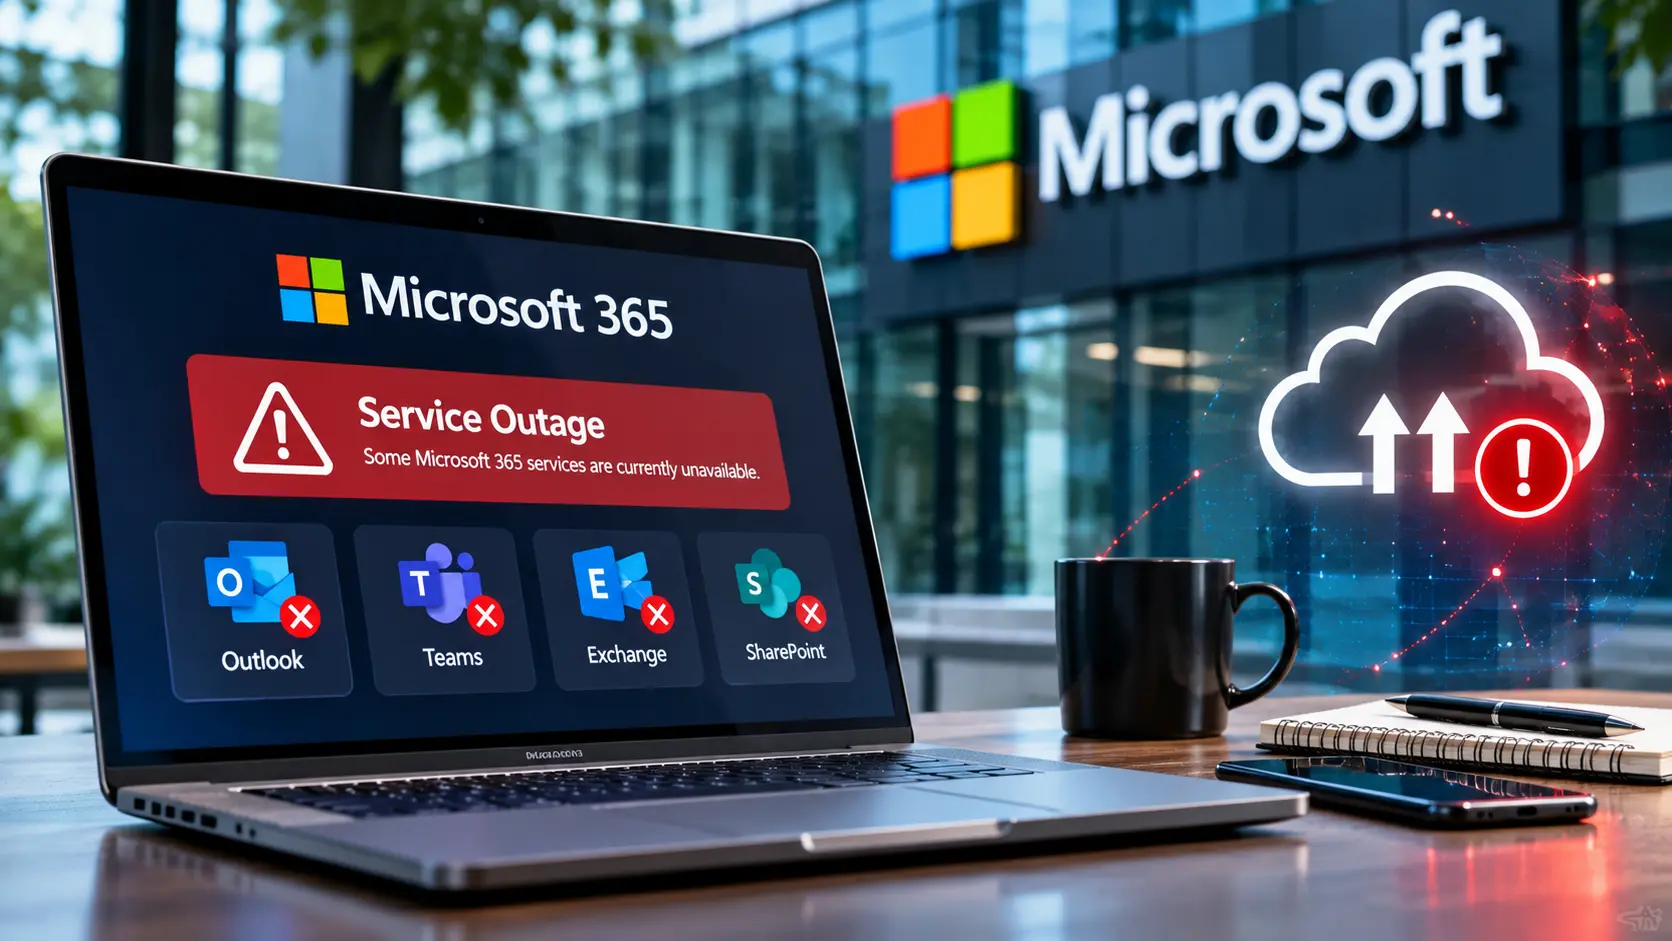
- Microsoft’s November 2026 outage disrupted Outlook, Exchange Online, Teams and other Microsoft 365 services across multiple regions.
- The incident exposed how network-capacity issues and interconnected cloud infrastructure can affect businesses even when backup systems and redundancy are in place.
- The disruption raises fresh questions about cloud dependency, business continuity and the resilience of AI-powered workplace platforms.
Microsoft 365 Outage: What Happened?
Microsoft faced a widespread service disruption beginning on November 12, 2026, affecting users attempting to access Outlook, Exchange Online and several other Microsoft 365 applications. The incident continued into November 13, with recovery efforts extending into November 14.
Tracked under incident reference MO1550821, the disruption affected multiple regions and interrupted email communication, workplace collaboration and business operations. A related Exchange Online incident was tracked under reference EX1550543.
The impact extended beyond individual users. Microsoft 365 services, including Teams, SharePoint, Copilot, Defender and other enterprise tools, experienced connectivity problems. Reports also highlighted difficulties for organisations that rely on Microsoft’s infrastructure for everyday operations.
According to the Associated Press, outage tracker Downdetector received reports from users across more than 70 countries and territories. The disruption also affected government offices, healthcare providers, businesses and financial institutions.
One example came from Japan’s Sanin West National Highway Office, which issued a public notice on November 13 stating that the Microsoft 365 disruption had affected its ability to send and receive emails. The office advised people to contact it by telephone and warned that incoming messages might not have been received.
What Caused Microsoft’s Global Outage?
Microsoft’s preliminary explanation points to a technical issue involving network capacity and infrastructure changes.
In its service updates, the company said an issue associated with an earlier network-capacity upgrade surfaced following a more recent network change. The affected servers became unresponsive as a core process was overwhelmed, reducing available capacity across the infrastructure.
Microsoft’s recovery efforts involved several steps:
- Restricting certain types of traffic reaching affected infrastructure.
- Investigating diagnostic data to identify the underlying problem.
- Rebuilding selected servers using an earlier software configuration.
- Applying configuration changes and restarting affected components.
- Gradually restoring traffic while monitoring server stability.
The recovery process proved more complicated than initially expected. Microsoft reported that some servers that had been brought back online became unresponsive again after receiving user traffic.
The company eventually confirmed on November 14 that it had addressed the underlying issue and restored services to the remaining affected customers and regions. It also stated that the incident was not related to a cyberattack or artificial intelligence agents.
Microsoft has indicated that a detailed post-incident report will provide further information about the root cause and corrective measures.
Why Were Backups Not Enough?
The disruption highlights an important distinction between having backup systems and maintaining uninterrupted service availability.
Large technology companies operate extensive infrastructure with multiple layers of redundancy. However, these arrangements cannot eliminate every operational risk.
Backups primarily protect copies of information so that data can be recovered following deletion, corruption or loss. Disaster recovery focuses on restoring systems after major failures, while high availability aims to minimise interruptions when individual components stop functioning.
A shared infrastructure problem can affect several interconnected systems simultaneously. For example, a network configuration issue or common software dependency may disrupt multiple services, even when alternative servers and backup resources are available.
Microsoft’s incident demonstrated how restoring infrastructure also requires careful traffic management and stability testing. Simply restarting servers does not guarantee that they will remain operational once normal demand returns.
Importantly, the available information does not establish that Microsoft lost customer data or lacked backups. The confirmed issue primarily concerned service availability and access.
The Business Risk of Depending on One Cloud Provider
For businesses, the incident raises a broader question: how much of their daily operations can continue when a major technology provider becomes unavailable?
Companies increasingly depend on a small number of technology platforms for email, document storage, meetings, identity management and customer communication. When these services are interconnected, a disruption in one part of the ecosystem can affect several business functions simultaneously.
Organisations can strengthen their continuity arrangements through:
- Alternative communication channels: Maintain phone-based contact lists and independent messaging options.
- Accessible document backups: Keep critical records, operating procedures and contact information available outside the primary cloud environment.
- Data export procedures: Regularly test whether emails, files and essential configurations can be retrieved and used.
- Manual operating procedures: Establish alternatives for approvals, customer support and urgent business decisions.
- Independent administration access: Ensure IT teams can obtain service updates even when the primary administration portal is unavailable.
Multi-cloud infrastructure is another possible approach, allowing organisations to distribute critical workloads across different providers. However, it can increase costs, technical complexity and cybersecurity requirements. Businesses need to assess which operations genuinely require independent infrastructure rather than adopting multiple providers without a clear purpose.
What Does the Outage Mean for Microsoft’s AI Business?
The disruption also arrives at a time when Microsoft is expanding artificial intelligence across its workplace ecosystem.
Microsoft Copilot and other AI-powered features are increasingly integrated into applications used for communication, productivity and enterprise operations. This creates additional dependencies on the underlying cloud infrastructure.
The outage also revived discussions around Elon Musk’s August 2025 remark that OpenAI could eventually challenge Microsoft’s position. However, that comment was made in a separate strategic context and was not a response to the November outage.
The broader question is whether AI agents will change the economics of traditional enterprise software. If users increasingly rely on AI systems to write documents, analyse information, develop code and manage workflows, competition could shift towards companies controlling AI models, distribution networks and computing infrastructure.
Microsoft is attempting to strengthen its position by integrating AI into Microsoft 365, developer tools and cloud services. The long-term opportunity will depend on whether these products generate sustainable revenue and strengthen customer relationships.
The November outage does not establish that Microsoft is losing its competitive position. Instead, it highlights an operational challenge that becomes increasingly important as businesses integrate more AI-powered services into their daily activities.
What Businesses and Investors Should Watch Next
Microsoft’s forthcoming post-incident report will be an important development, particularly its explanation of the network-capacity issue and the corrective measures introduced to prevent similar disruptions.
Businesses should also evaluate their dependence on individual technology providers and test whether their continuity arrangements can withstand prolonged service interruptions.
For investors, the incident brings attention to Microsoft’s infrastructure reliability, enterprise customer confidence and the economics of its AI investments. However, one outage alone is insufficient to establish a lasting change in the company’s competitive position.
The bigger takeaway is that cloud infrastructure is no longer simply an IT requirement. It has become a critical part of business continuity. As artificial intelligence and cloud-based applications become more deeply integrated into the global economy, the ability to maintain operations during disruptions will become an increasingly important measure of technology resilience.
Disclaimer: This article is for information purposes only and is not investment advice.
For more such information, visit EQMint
Join our WhatsApp channel for timely updates: Whatsapp.